[TWITTER]
Sep 23
Cursor@cursor_ai

We've reduced token costs in Cursor by 7% with no drop in agent quality. Savings came from tighter prompts, selective tool loading, better caching, and compressed file reads.

Things I stumbled upon that caught my attention
We've reduced token costs in Cursor by 7% with no drop in agent quality. Savings came from tighter prompts, selective tool loading, better caching, and compressed file reads.
Muse, Instinct, OpenClaw, Claude Code… All successful agents have 3 key components: 🧠 Brain → model, harness (logic) 👐 Hands → tools, computer, browser 🗃️ Files → memories, skills, repos The 'easy' way is to throw all these in 1 stateful computer (a Mac Mini) Like, you run 𝚌𝚕𝚊𝚞𝚍𝚎 or 𝚏𝚡 in your mac, you keep it running all day with 𝚌𝚊𝚏𝚏𝚎𝚒𝚗𝚊𝚝𝚎, it has storage, and CLIs and apps installed. But if you want to cost-efficiently run agents in the cloud, you actually start breaking down these parts. 🧠 The harness can run in Fluid compute. To make it reliable across restarts,…
Vercel Sandbox now has persistent storage with Drives, in public beta on every plan. ▪︎ Store agent workspaces, data, models, deps ▪︎ Read snapshots across parallel sandboxes ▪︎ Mount up to four Drives per sandbox ▪︎ Up to 16 TiB per Drive https://vercel.com/changelog/drives-for-vercel-sandbox-are-now-in-public-beta
Introducing Arrow 2 Our latest and most advanced models for generating precise, editable vector graphics. Higher quality. Faster outputs. Available now in App and API.

Weekly picks
My (human) thoughts on what I think matters and why. No AI slop.
No ads. No bullshit. Unsubscribe anytime.

Today, Waymo is excited to announce our transit rewards program, which we will initially offer in the San Francisco Bay Area, with future cities to follow. This first-of-its-kind initiative rewards riders with Waymo Cash when they connect their Waymo rides with public transit and use their Visa card.
Next version of OpenClaw uses a decision model to automatically decide between steer or queue. (Lab feature, we support Jef* and API-compat (e.g. local models like Kef...) and ONNX variants)

AI is getting cheaper more quickly than any other transformative tech in history. At a given level of performance, cost has fallen ~47%/quarter since 2023. That’s 4× faster than DNA sequencing, 6× faster than compute, 18× faster than lithium batteries, and (up to 1973) 54× faster than electricity.

Anthropic Technical Staff Thariq Shihipar says a smarter model needs a heavier harness, not a lighter one "The harness is super important. Sometimes there's this idea that the harness doesn't matter, because the models will get better and better." "And if the model just does everything perfectly, then why do you need a harness at all?" "And in practice, what we see is the models get better and better. And so the harness needs to become more and more complicated to allow the model to do more things." "And an example of this is auto mode. Auto mode is a classifier that runs after every task…

Anthropic Technical Staff Jess Yan says the harness and the model cannot be pulled apart without giving up performance, though she flags her own bias. "I think I am quite biased but I also think that it is impossible to get the maximum possible performance without tying together the harness and the model." "Now the components of the harness and maybe the thickness of the harness will change over time as models get more and more capable." "However, when we test our models and when we are assessing their performance we always have to test it in conjunction with a harness." "And are we going to test it with all the different harnesses of the world? We're going to select the harnesses that we have built." "And so there is an aspect of the necessity of building models is that you have to be testing them with harnesses, and that sort of keeps them paired together."
Deepdive into the Windows team’s efforts to make the OS “AI agent-friendly” and win back developers by going all-in on Linux on Windows, local models, GPUs, & more

Claude Opus 5.5 leads in agentic coding and knowledge work, and costs 40% less to run than Opus 5 on typical workloads.
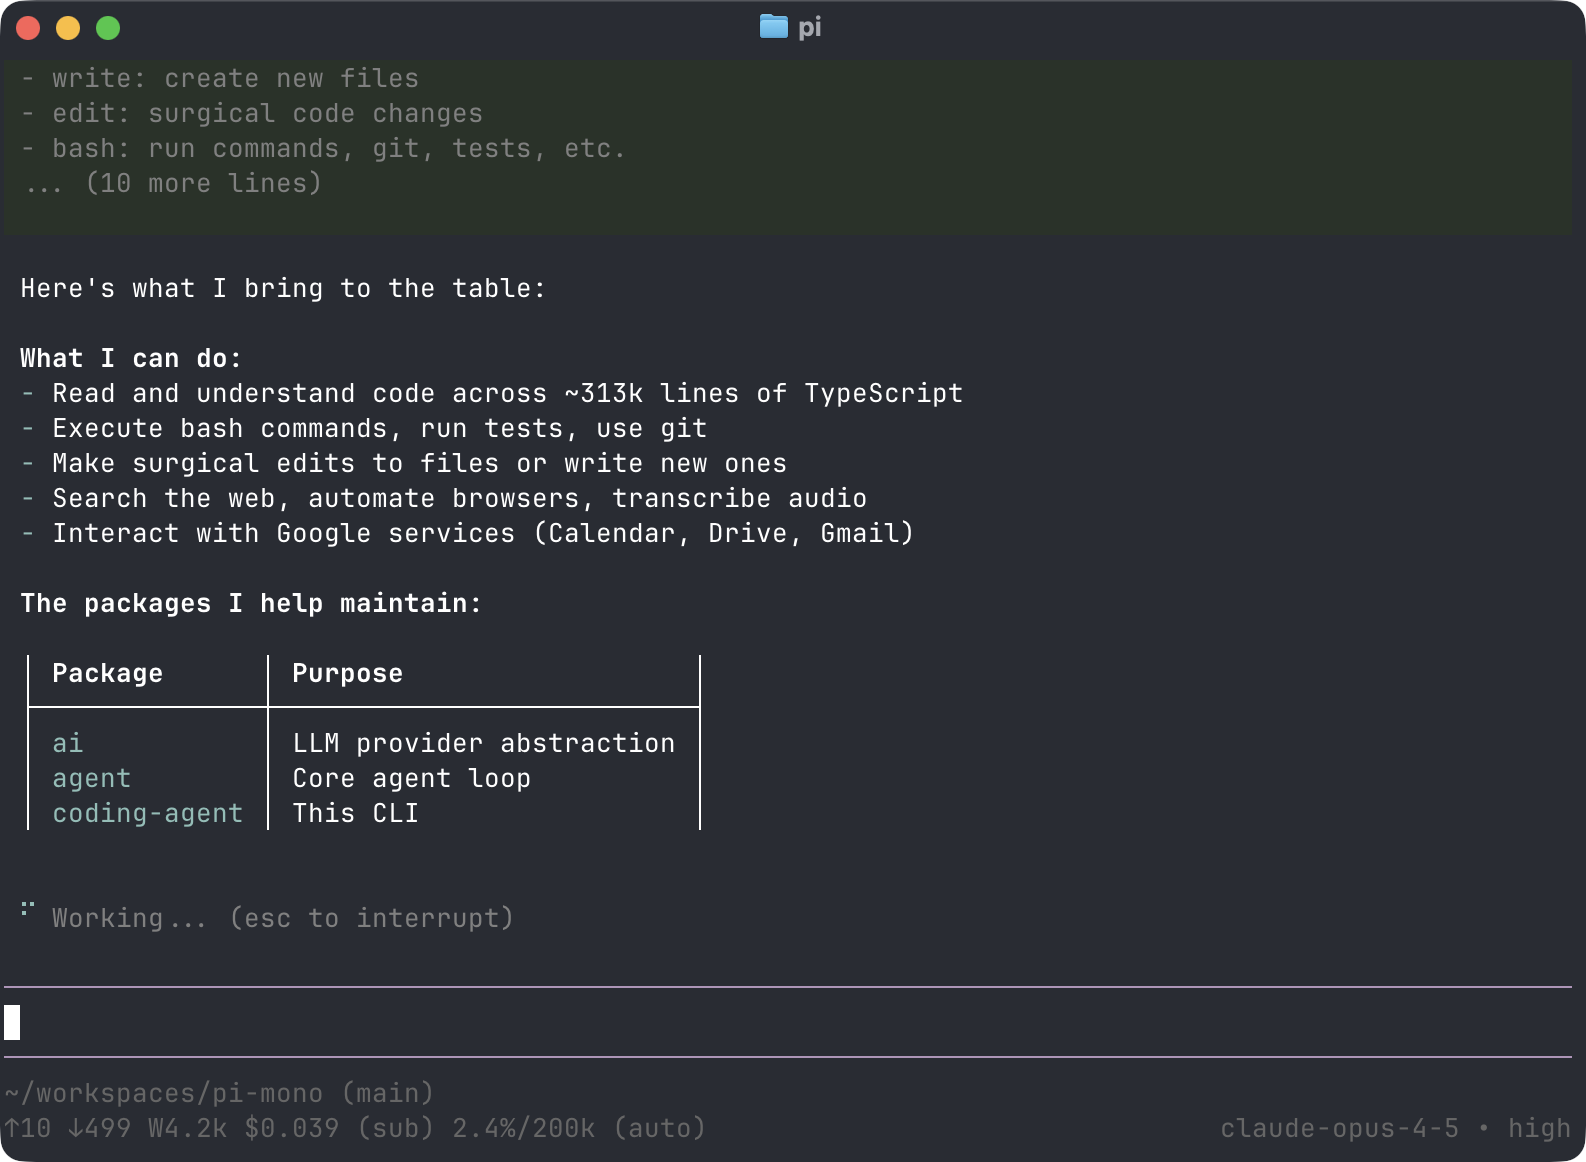
A terminal-based coding agent
Today we introduce JetBrains Air - the product system for software development orgs in the age of agents. Built for developers, team leads & engineering directors. Open and flexible: steer and control almost any LLM & harness. Read more: https://jb.gg/air-announce

Most models of major.minor version means the major version is a pre train checkpoint and the minor is a post train. The post training makes the model more “agentic” but not truly more intelligent. It has just been tortured to “think out loud” for longer. But that said no one ones when you’ve “saturated” the raw intelligence of the pre trained base model until you actually reach there. The point where the the + 0.1 releases increase very little on benchmark but a lot on tokens means it is time to pretrain a new model.

The diff in intelligence v/s output tokens for Grok 4.6 to Grok 4.7
The subtle pleasure of hot reloading, and how OpenCode keeps its environment changing while the agent keeps working.
A pivotal moment for real estate! 🏡 Capturing a property in 3D used to mean a $5,000 LiDAR scanner. This house was scanned with a $500 @insta360 X5 - a consumer 360 camera. And best of all? All of the software is free and open source! It's based on a technique called 3D Gaussian splatting: 🪄 Splat creation: Spirula Studio 🖼️ Splat rendering: @PlayCanvas So for $500, you can present any property online and let prospective purchasers freely explore as if it was a videogame. 🎮 [1/3]

Most companies that shut down give up their impact. This startup did something much better: they open-sourced 1,274 hours of egocentric robotics data. 13,451 recordings of humans doing everyday tasks, as a gift to the robotics community. Thank you @eidon_ai! Open source has a superpower: work can outlive the organization that created it. More startups should do this! https://huggingface.co/eidon-ai

Code reviews today are mostly about gut checking if the complexity is worth the benefits.

This is NOT Jev. Open source. Runs on your laptop. Decides in ~27 ms, about 200× faster than waiting on a hosted LLM. Here it is playing Tetris by itself 👇 https://brainfunctioncollapse.com/laya

Self-hosted an open decision model on my Proxmox box, then ran it head to head against the paid one on the same 520 labelled examples from our invoicing SaaS. ▎Jev won 19 of 20 questions. Laya scored at chance on 6 of them — including the tax treatment question, where being wrong has legal consequences. The most useful finding wasn't the winner. With option keys named R1…R5, Laya scored 15.7% — below chance — and answered R5 to 48 of 51 examples. Renaming them to credito_incobrable and friends took it to 43%. Reorder the options and the answer changes entirely. ▎ The key name isn't metadat…

Put localhost on the Internet with a free, encrypted Cloudflare Quick Tunnel. No account, DNS, or open ports required.
Grok 4.7 is here. It's a notable improvement over Grok 4.6 at the same price and speed.

Grok 4.7 works longer on difficult tasks, checks its work more carefully, and comes with our strongest safeguards to date.


I’m excited about a future that I suspect will be very hard on many long-time friends and certain people that I love. The same technology that is allowing me to be more successful than ever is
here's how i shipped 2,500 PRs last month to production this was originally supposed to be for Cursor Compile in London. i couldn't make it since i was livestreaming for Grok @Bot Galaxy so i'm making it available for free here on X! watch it on 2x speed, i talk slowly

Looks like today may be a record day for token volume % of open models on Vercel AI Gateway: 🟦 Open 78.4% 🟨 Closed 21.6% While spend 💲 usually tells a different story, #3 and #4 today are Moonshot AI & DeepSeek. Adding Z.ai, their combined spend surpasses OpenAI (#2). (Do note that's the spend for inference of the model across providers (mostly in the US), not revenue going directly to the open weight labs.)

Why Hollywood is using Seedance 2.5 and Seedance 2.0 Part 3. #DreaminaCPP #DreaminaAi #Seedance25 @dreamina_ai

This is exactly why Hollywood didn’t ban Seedance 2.0 and Seedance 2.5. They’re using it instead. #DreaminaCPP #DreaminaAi
What when it comes to AI in software engineering are you struggling with the most?
Multi tasking. Flow state is kinda gone and it seems like the best I can get now feels more like playing a late game RTS match where you need to make sure you dont get idle villagers while you're microing other 5 groups of units in different places of the map. An RTS match only lasts 30min though.
Self-learning harnesses are here. After @deepseek_ai released their new harness, even the authors of Pi & OpenCode said there were some super compelling ideas in there. But what exactly? @IurySza and I take a shot at explaining it in @FragmentedCast

What when it comes to AI in software engineering are you struggling with the most?
First experiment with @typesafeai's Jev A semantic log filter. (with a CLI that lets my agent use it too) Ofc, I had to overdoit and build a TUI around it :)

Lazy work used to mean too little output. Now, with AI, it often means too much and more work for everyone else. @tobi call it "slop grenades." A "Slop Grenade" is when you let AI produce the work and pass it on without adding any value (including checking it). Someone else has to wade through it, catch the mistakes, and clean up the mess. You save time and look productive but someone else pays for it.

My third conversation with Shopify co-founder and CEO @tobi. 0:00 How Shopify Uses AI 7:18 River: Shopify's Internal AI 8:55 How to Encourage Osmosis Learning 10:52 AI Dreaming and Self-Reflection 11:53 How to Use AI for Strategic Decision Making 14:11 The One Thing AI Cannot Do 16:04 What AI is Making Worse at Shopify 19:46 Predictions: Where AI is Headed Next 21:55 The Future of AI-Powered Software 24:40 Will CEOs Be Replaced with AI? 27:54 Can Superintelligence Be Controlled? 31:13 Critical Skills in AI Age 34:22 Why Complex Solutions are Usually Wrong 36:33 Conditions Needed for True Intuition 38:02 The Best Path Doesn't Have Instant Feedback 44:51 How Affirmations Can Shift Your Behavior 50:44 The Inobvious Thing Hurting Companies 52:37 Relationship Between Beauty and Creation 56:23 How SpaceX Moves Forward By Subtraction 1:00:24 Why Companies Need Refounding Events 1:01:50 Books as Cheat Codes 1:02:39 Three Books to Change Your Thinking Enjoy! (Includes paid promotions.)
Most predictions I see are still way too conservative. Here's mine

Made a real-time slop detector with jev as you scroll

MCP vs CLI for LLMs is the wrong discussion. People are debating at the wrong layer. Both work incredibly well as long as they are run through a repl like environment that can persist state. The funny thing about CLI is that CLI tools are usually accessed through BASH which happens to be a repl with persistent state (the file system), therefore cli works much better than mcp. But this isn't even close to being an intrinsic property of MCP. Just means that we need better harnesses. Right now the best repl for this are: - bash + fs - jupyter kernels - codemode type repls, usually quickjs LLM…
pi-subagents now has code mode. 🥳 Orchestrate subagents with plain JavaScript: loop, fan out, await, branch on real child output. Mix parallel and sequential phases, and isolate every child in its own git worktree, all in one script. https://github.com/nicobailon/pi-subagents pi install npm:pi-subagents

Summoning People of @pidotdev! Been thinking about building this for a while and now it's here! Powered by the new @ChatGPT Live API (released last week) You talk to one skipper. That person delegates to the other agents, and you can keep up with the threads. For brainstorming, bouncing ideas, getting a status update while you walk around, it is just a nice interface. You dont even have to sit at the computer. You can interrupt and brainstorm live. Voice mode on its own has always super limited. But this last generation is actually amazing! These models are still not super smart, and they…

OpenClaw 2.0 has arrived https://openclaw.ai/blog/openclaw-2-accidentally

Episode 101 is live! 🎙️ We're diving into Coding Agents with mobile dev & platform engineer @IurySza. We explore agentic dev setups, shaping context with AGENTS.md, and the reality of running local models. Listen to it here: https://thebakery.dev/101/

This is a continuation of this mailing list thread about "fully LLM-generated merge requests, preserved at https://mail.kde.org/pipermail/kde-devel/2026-September/004496.html There, I proposed...
From Tibo @thsottiaux, “It just goes out to a billion users and it's fine”. How OpenAI engineers can still ship the same day: "Even though ChatGPT goes out to a billion active users, you can ship a PR, you can make a change and get it shipped the next day or even the same day. And it just goes out to a billion users and it's fine. We just really instill a sense of ownership and care. So people are very empowered to make changes, even large changes. The general thing that is being asked is evidence that it's going to be well received, evidence that it's a worthy addition, evidence that it is…

The U.S. is slouching toward heavy regulation while China is poised to rush ahead, writes Tyler Cowen. Beijing will then dominate everything from global arms sales to healthcare.
I am done with this shit. It is over. The state of engineering right now is horrible. It has been half a month since I started a new role at a big company. Nobody knows anything here. The specs, code, tests, PRDs, tickets, resolution of those tickets, reports, etc., everything is made by Claude Code. Nobody on my team likes this. They are being forced to ship as much as they can. I have heard multiple times from higher management that pushing code is not a bottleneck, so why are we slow? People are working 12 to 13 hours a day just to press enter. Nobody is reading anything. Humans in corporat…
*taps the sign*

The problem with all of these AI personal assistant things is that people don’t actually want to do stuff. You fucking get that right? Do you understand that? Just like AI tools in the workforce, AI assistants don’t actually abstract decisions for you, they let you accelerate decision making. So instead of making one decision a day and then lamenting you can’t do more, AI assistants are going to let you make ten decisions a day and act on all of them. A miracle? Nah dog, a fucking nightmare. Nobody except type A strivers who need Twitter fodder actually want that. Let me tell you a story. When I got back from college I was inspired. If I could take on an elite university with grit and determination, so could everyone I know. I was all razzed up to get people I know to achieve their potential. What I learned after many years of trying is that absolutely nobody wants to realize their potential. People want to hang out with friends and complain. That’s how the world has worked for ten thousand years. This weather fucks. Can you believe the cows walked off. People don’t want enablement. People don’t want you to take all of their excuses. TV is mindless passive activity. AI assistants are not. They’re telling people that they can achieve more. And people absolutely do not want that. Let me tell you another story. Once upon a time I lead a big process overhaul at work and it was great. Two years later I hired a contractor to do something similar. But I personally didn’t want to have to do a bunch of work. Within a week I knew I fucked in. This contractor kept coming to me with decisions I needed to make. Dude I wanted to not have to think about this. Again, a helper when you don’t actually want help is a disaster. None of these AI assistants will take off because people don’t actually want assistants.

We’re on a journey to advance and democratize artificial intelligence through open source and open science.